July 25, 2012

NRL Predictions, Round 21

Team Ratings for Round 21

Here are the team ratings prior to Round 21, along with the ratings at the start of the season. I have created a brief description of the method I use for predicting rugby games. Go to my Department home page to see this.

Current Rating Rating at Season Start Difference
Bulldogs 7.75 -1.86 9.60
Rabbitohs 3.99 0.04 3.90
Warriors 3.65 5.28 -1.60
Broncos 3.45 5.57 -2.10
Cowboys 3.36 -1.32 4.70
Storm 3.09 4.63 -1.50
Sea Eagles 2.29 9.83 -7.50
Wests Tigers -0.26 4.52 -4.80
Knights -0.61 0.77 -1.40
Raiders -1.78 -8.40 6.60
Titans -1.90 -11.80 9.90
Dragons -3.07 4.36 -7.40
Sharks -4.28 -7.97 3.70
Roosters -5.26 0.25 -5.50
Panthers -6.87 -3.40 -3.50
Eels -7.28 -4.23 -3.00


Performance So Far

So far there have been 144 matches played, 84 of which were correctly predicted, a success rate of 58.33%.

Here are the predictions for last week’s games.

Game Date Score Prediction Correct
1 Sea Eagles vs. Bulldogs Jul 20 12 – 20 0.37 FALSE
2 Titans vs. Broncos Jul 20 14 – 10 -1.77 FALSE
3 Warriors vs. Knights Jul 21 19 – 24 11.38 FALSE
4 Eels vs. Storm Jul 21 16 – 10 -8.13 FALSE
5 Rabbitohs vs. Dragons Jul 21 36 – 14 9.58 TRUE
6 Sharks vs. Raiders Jul 22 4 – 36 8.47 FALSE
7 Panthers vs. Roosters Jul 22 28 – 16 1.16 TRUE
8 Cowboys vs. Wests Tigers Jul 23 29 – 16 7.19 TRUE


Predictions for Round 21

Here are the predictions for Round 21

Game Date Winner Prediction
1 Dragons vs. Storm Jul 27 Storm -1.70
2 Roosters vs. Titans Jul 27 Roosters 1.10
3 Bulldogs vs. Cowboys Jul 28 Bulldogs 8.90
4 Sea Eagles vs. Warriors Jul 28 Warriors -1.40
5 Sharks vs. Panthers Jul 28 Sharks 7.10
6 Raiders vs. Knights Jul 29 Raiders 3.30
7 Rabbitohs vs. Wests Tigers Jul 29 Rabbitohs 8.80
8 Broncos vs. Eels Jul 30 Broncos 15.20


Super 15 Predictions, Week 23

Team Ratings for Week 23

Here are the team ratings prior to Week 23, along with the ratings at the start of the season. I have created a brief description of the method I use for predicting rugby games. Go to my Department home page to see this.

Current Rating Rating at Season Start Difference
Crusaders 9.41 10.46 -1.10
Sharks 5.91 0.87 5.00
Stormers 4.55 6.59 -2.00
Hurricanes 3.40 -1.90 5.30
Chiefs 3.09 -1.17 4.30
Bulls 2.93 4.16 -1.20
Reds 0.41 5.03 -4.60
Brumbies -0.89 -6.66 5.80
Blues -2.77 2.87 -5.60
Waratahs -3.13 4.98 -8.10
Highlanders -3.17 -5.69 2.50
Cheetahs -3.99 -1.46 -2.50
Lions -8.75 -10.82 2.10
Force -9.18 -4.95 -4.20
Rebels -11.11 -15.64 4.50


Performance So Far

So far there have been 122 matches played, 87 of which were correctly predicted, a success rate of 71.3%.

Here are the predictions for last week’s games.

Game Date Score Prediction Correct
1 Crusaders vs. Bulls Jul 21 28 – 13 10.20 TRUE
2 Reds vs. Sharks Jul 21 17 – 30 1.30 FALSE


Predictions for Week 23

Here are the predictions for Week 23. The prediction is my estimated points difference with a positive margin being a win to the home team, and a negative margin a win to the away team.

Game Date Winner Prediction
1 Chiefs vs. Crusaders Jul 27 Crusaders -1.80
2 Stormers vs. Sharks Jul 28 Stormers 3.10


July 23, 2012

Road toll stable

From the Herald this morning

More people have died in fewer car smashes since January 1 than at this time last year, prompting a Government reminder about the responsibility drivers hold over others’ lives.

“The message for drivers is clear,” Associate Transport Minister Simon Bridges said yesterday of a spate of multi-fatality crashes that have boosted the road toll to 161.

The number of fatal crashes is 133, compared to 144 last year at this time, and the number of deaths is 161, compared to 155 last year.

How do we calculate how much random variation would be expected in counts such as these?  It’s not sampling error in the sense of opinion polls, since these really are all the crashes in New Zealand.  We need a mathematical model for how much the numbers would vary if nothing much had changed.

The simplest mathematical model for counts is the Poisson process.  If dying in a car crash is independent for any two people in NZ, and the chance is small for any person (but not necessarily the same for different people) then number of deaths over any specified time period will follow a Poisson distribution.    The model cannot be exactly right — multiple fatalities would be much rarer if it were — but it is a good approximation, and any more detailed model would lead to more random variation in the road toll than the Poisson process does.

There’s a simple trick to calculate a 95% confidence interval for a Poisson distribution, analogous to the margin of error in opinion polls.  Take the square root of the count, add and subtract 1 to get upper and lower bounds, and square them: a count of 144  is consistent with underlying averages rates from 121 to 169.   And, as with opinion polls, when you look at differences between two years the range of random variation is about 1.4 times larger.

Last year we had an unusually low road toll, well below what could be attributed to random variation.  It still isn’t clear why, not that anyone’s complaining.  The numbers this year look about as different from last year’s as you would expect purely by chance.  If the message for drivers is clear, it’s only because the basic message is always the same:

yellow road sign: You're in a box on wheels hurtling along several times faster than evolution could have prepared you to go

Stat of the Week Winner

No winner this week but thank you for your nominations. Please continue to nominate!

Stat of the Week Competition: July 21 – 27 2012

Each week, we would like to invite readers of Stats Chat to submit nominations for our Stat of the Week competition and be in with the chance to win an iTunes voucher.

Here’s how it works:

  • Anyone may add a comment on this post to nominate their Stat of the Week candidate before midday Friday July 27 2012.
  • Statistics can be bad, exemplary or fascinating.
  • The statistic must be in the NZ media during the period of July 21 – 27 2012 inclusive.
  • Quote the statistic, when and where it was published and tell us why it should be our Stat of the Week.

Next Monday at midday we’ll announce the winner of this week’s Stat of the Week competition, and start a new one.

(more…)

July 21, 2012

Best practice guidelines: a worked example

Stuff has a headline “Living by the sea is good for your health” (with the page title “Life’s a beach”). The story starts

Sick people have been sent to the seaside for centuries and now a study has proven that living by the coast is good for your health.

Let’s see how it rates against the guidelines

(more…)

Best-practice guidelines for science reporting

These are from the UK Science Media Centre, part of its submission to the Leveson Inquiry

  • State the source of the story – e.g. interview, conference, journal article, a survey from a charity or trade body, etc. – ideally with enough information for readers to look it up or a web link.
  •  Specify the size and nature of the study – e.g. who/what were the subjects, how long did it last, what was tested or was it an observation? If space, mention the major limitations.
  • When reporting a link between two things, indicate whether or not there is evidence that one causes the other.
  • Give a sense of the stage of the research – e.g. cells in a laboratory or trials in humans – and a realistic time-frame for any new treatment or technology.
  •  On health risks, include the absolute risk whenever it is available in the press release or the research paper – i.e. if ’cupcakes double cancer risk’ state the outright risk of that cancer, with and without cupcakes.
  •  Especially on a story with public health implications, try to frame a new finding in the context of other evidence – e.g. does it reinforce or conflict with previous studies? If it attracts serious scientific concerns, they should not be ignored.
  •  If space, quote both the researchers themselves and external sources with appropriate expertise. Be wary of scientists and press releases over-claiming for studies.
  • Distinguish between findings and interpretation or extrapolation; don’t suggest health advice if none has been offered.
  •  Remember patients: don’t call something a ’cure’ that is not a cure.
  • Headlines should not mislead the reader about a story’s contents and quotation marks should not be used to dress up overstatement

This blog would be a lot less interesting (except to rugby fans) if the media followed these guidelines.  I think the second-last item is the only one that hasn’t been the basis for one or more posts.     (via)

One of these countries is different

You will have heard about the terrible shootings in Colorado.

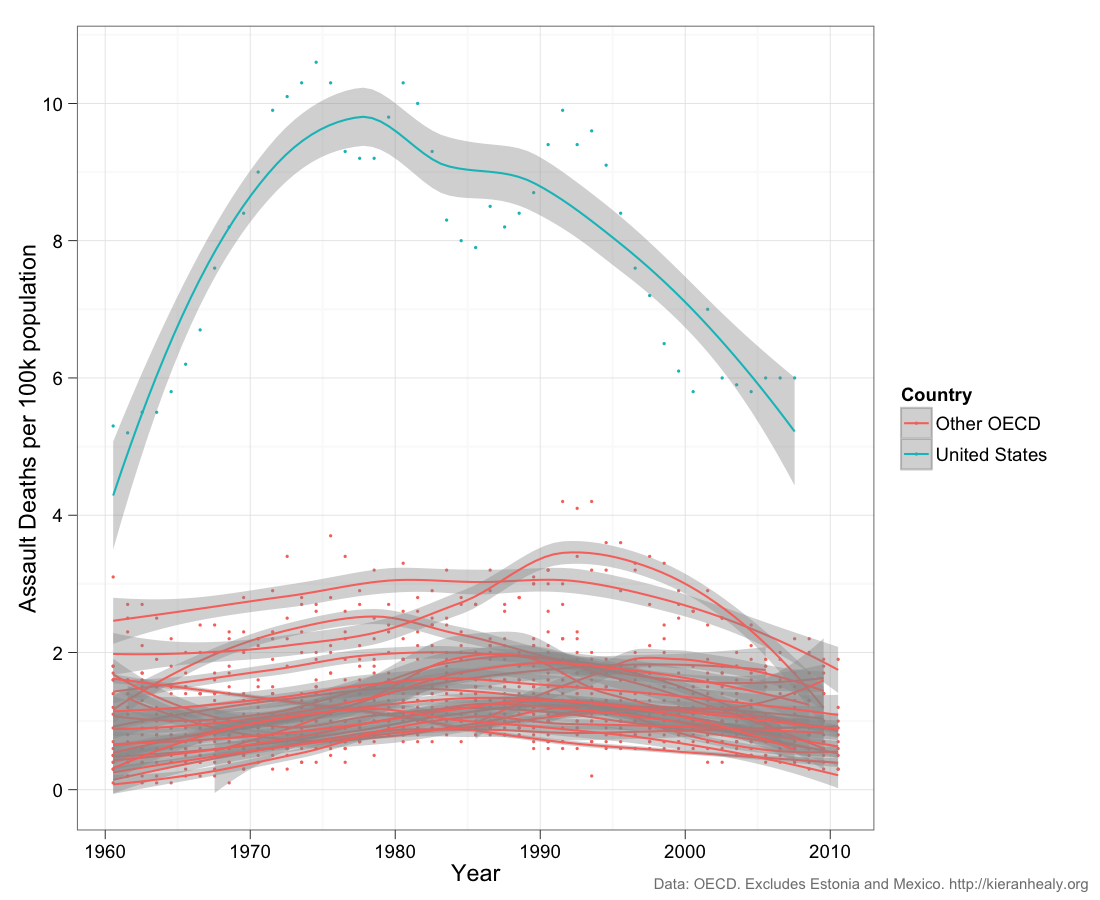
From a post by Kieran Healy, at Crooked Timber, responding to the tragedy: death rates from assault, per 100,000 population per year, for the US and 19 other OECD countries.  New Zealand is roughly in the middle (his post gives separate plots for each country).  Dots are the data for individual years, the curves are smoothed trends with margin of error.

The much higher rate in the US is obvious, but so is the decline.


Part of the decline is attributable to better medical treatment, so that assault victims are less likely to die, but far from all of it.  The rate of reports of aggravated assault is also down over the same time period.  Similarly, simple explanations like gun availability probably contribute but can’t explain the whole pattern.

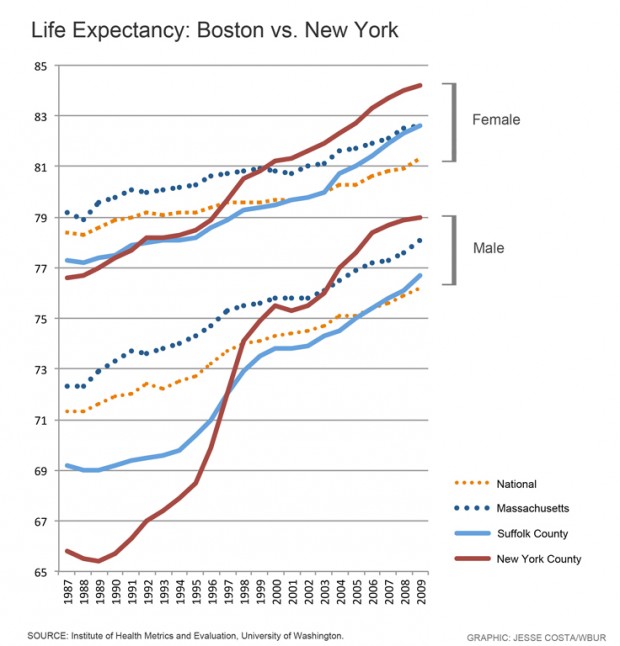
The decline in violent deaths is so large that it shows up in life expectancy comparisons.  New York, and especially Manhattan, used to have noticeably worse life expectancy than Boston, but the falling rate of violent deaths and the improvements in HIV treatment now put Manhattan, and the rest of New York City, at the top of US life expectancy

July 20, 2012

Measurement error and rare events

Surveys are not perfect: some people misunderstand the question, some people recall incorrectly, some responses are written down incorrectly by the poller, and some people just lie.   These biases happen in both directions, but their impact is not symmetrical.

Suppose you had a survey that asked “Have you ever been abducted by aliens?”  We can be sure that false ‘Yes’ results will be more common than false ‘No’ results, so the survey will necessarily overestimate the true proportion. If you wrote down the wrong answer for 1% of people, you’d end up with an estimate that was 1% too high.

In principle, the same issue  could be a serious problem in estimating the support for minor parties: about 1% of people voted for ACT at the last election, and 99% didn’t.  Suppose you poll 10000 people and ask them if they voted for ACT, and suppose that 100 of them really were ACT voters. If your opinion poll gets the wrong answer, randomly, for 1% of people, you will get the wrong answer from 1 of the true ACT voters, and 99 of the true non-ACT voters, so you will report 100+99-1=198 ACT voters and 9900+1-99 = 9802 non-ACT voters.  You would overestimate the votes for ACT by a factor of two!  Keith Humphreys, who we have linked to before, postulates that this is why US polls indicating support for a third-party candidate tend to seriously overestimate their support.

I’m skeptical.  Here in NZ, where we really have minor parties, there is no systematic tendency to overestimate the support they receive.  ACT got 1% of the vote, and that was close to what the polls predicted. Similarly, the Maori Party, and the Greens received about the same number of votes in the last election as averages of the polls had predicted.  For NZ First, the election vote was actually higher than in the opinion polls.  Similarly, for the Dutch general election in 2010 there was pretty good agreement between the last polls and the election results.  Even in Australia, where there is effectively a two-party system in the lower house (but with preferential voting), the opinion poll figures for the Greens agreed pretty well with the actual vote

It’s true that measurement error tends to bias towards 50%, and this matters in some surveys, but I would have guessed the US phantom third party support is the result of bias, not error. That is, I suspect people tend to overstate their support for third-party candidates in advance of the election, and that in the actual election they vote strategically for whichever of the major parties they dislike least.   My hypothesis would imply not much bias in countries where minor-party votes matter, and more bias in countries with first-past-the-post voting.  Unfortunately there’s also a pure measurement error hypothesis that’s consistent with the data, which is that people are just more careful about measuring minor-party votes in countries where they matter.

July 18, 2012

Global Innovation Barchart

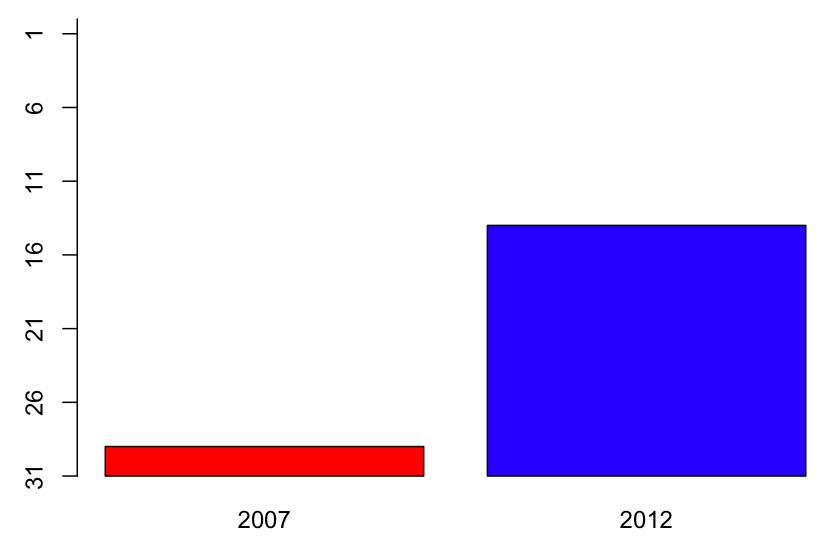
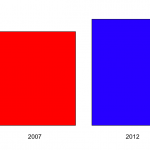
So.  The 2012 Global Innovation Index is out and NZ looks quite good.  Our only Prime Minister has a graph on his Facebook page that looks basically like this.


The graph shows that NZ was at rank 28 in 2007 and is now at rank 13.

A bar chart for two data points is a bit weird, though not nearly as bad as the Romney campaign’s efforts at Venn diagrams in the US.

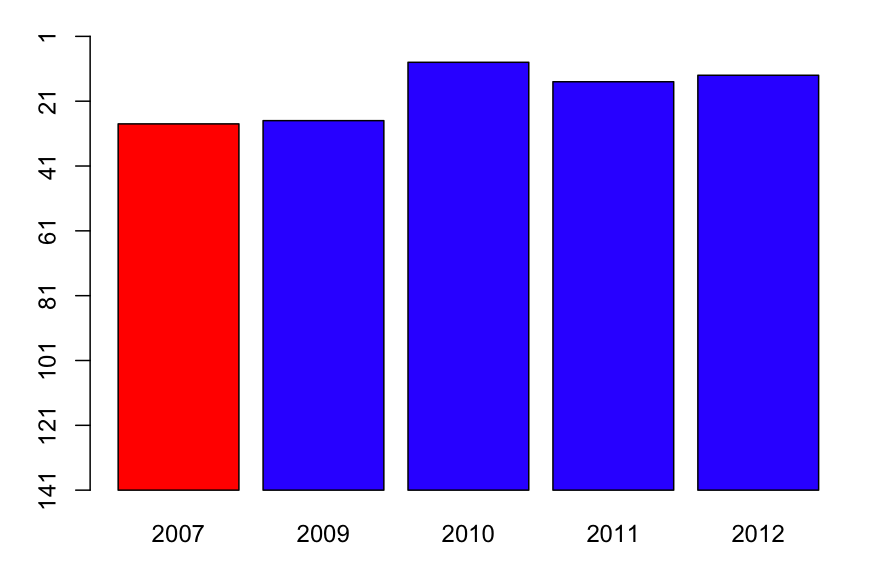
The scaling is also a bit strange.  The y-axis runs from 1 to 30, but there’s nothing special about rank 30 on this index. If we run the y-axis all the way down to 141 (Sudan), we get the second graph on the right, which shows that New Zealand, compared to countries across the world, has always been doing pretty well.


Now, there are some years missing on the plot, and the Global Innovation Index was reported for most of them.  Using the complete data, we get a graph like

So, in fact, NZ was doing even better on this index in 2010, and we get some idea of the year-to-year fluctuations.   Now, a barchart is an inefficient way to display data with just one short time series like this: a table would be better.

More important, though, what is this index measuring.  Mr Key’s Facebook page doesn’t say. Some of the commenters do say, but incorrectly (for example, one says that it’s based on current government policies).  In fact, the  exact things that go into the index change every year.  For example, the 2012 index includes Wikipedia edits and Youtube uploads,  in early years internet access and telephone access were included.  There are also changes in definitions: in early years, values were measured in US$, now they are in purchasing-power parity adjusted dollars.

Some of the items (such as internet and telephone access) are definitely good, others (such as number of researchers and research expenditure) are good all things being equal, and for others (eg, cost of redundancy dismissal in weeks of pay, liberalised foreign investment laws) it’s definitely a matter of opinion.Some of the items are under the immediate control of the government (eg public education expenditure per pupil, tariffs), some can be influenced directly by government (eg, gross R&D funding, quality of trade and transport infrastructure), and some are really hard for governments to improve  in the short term (rule of law, GMAT mean test score, high-tech exports, Gini index).

Since the content and weighting varies each year, it’s hard to make good comparisons. On the plus side, the weighting clearly isn’t rigged to make National look good — the people who come up with the index couldn’t care less about New Zealand — but the same irrelevance will also tend to make the results for New Zealand more variable.   Some of the items in the index will have been affected by the global financial crisis and the Eurozone problems. New Zealand will look relatively better on these items, for reasons that are not primarily the responsibility of the current governments even in those countries, let alone here.

I’d hoped to track down why New Zealand had moved up in the rankings, to see if it was on indicators that the current administration could reasonably take credit for, but the variability in definitions makes it very hard to compare.